Summary
-
ESSENTIAL-WEB V1.0, a 24-trillion-token dataset with expressive and extensive metadata at a document-level.
- This metadata includes subject matter, web page type, content complexity, and document quality
-
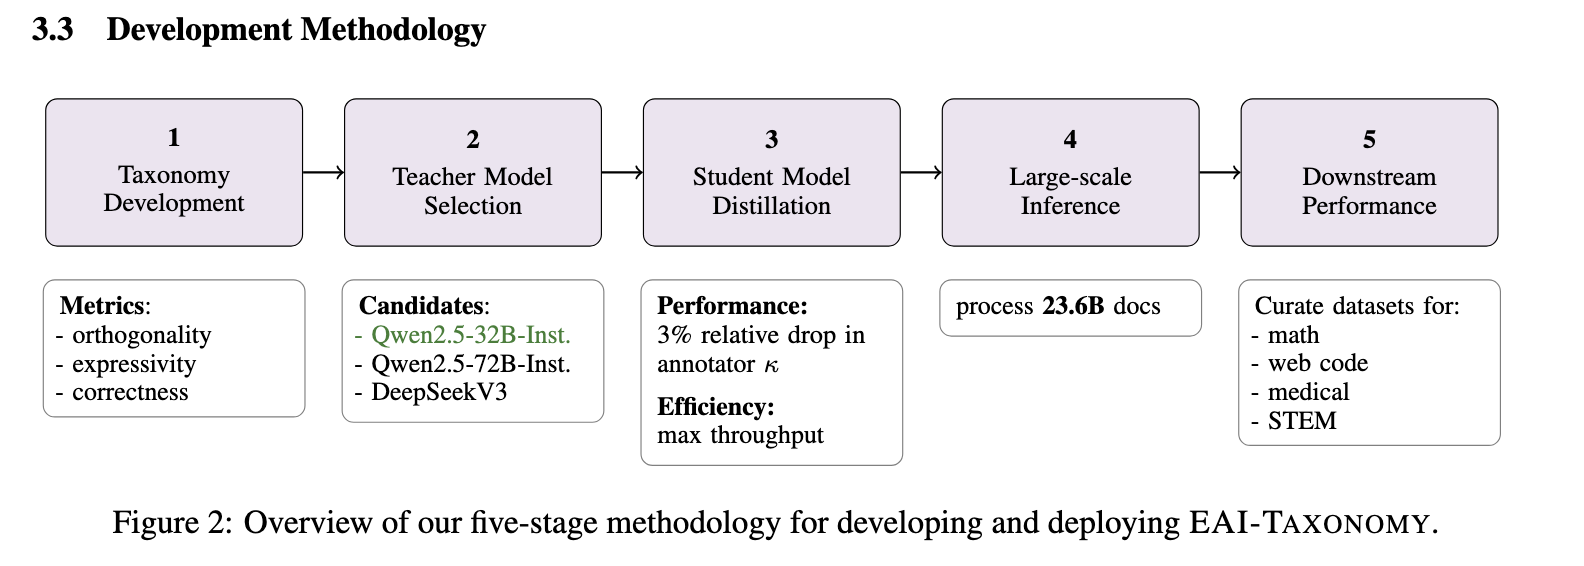
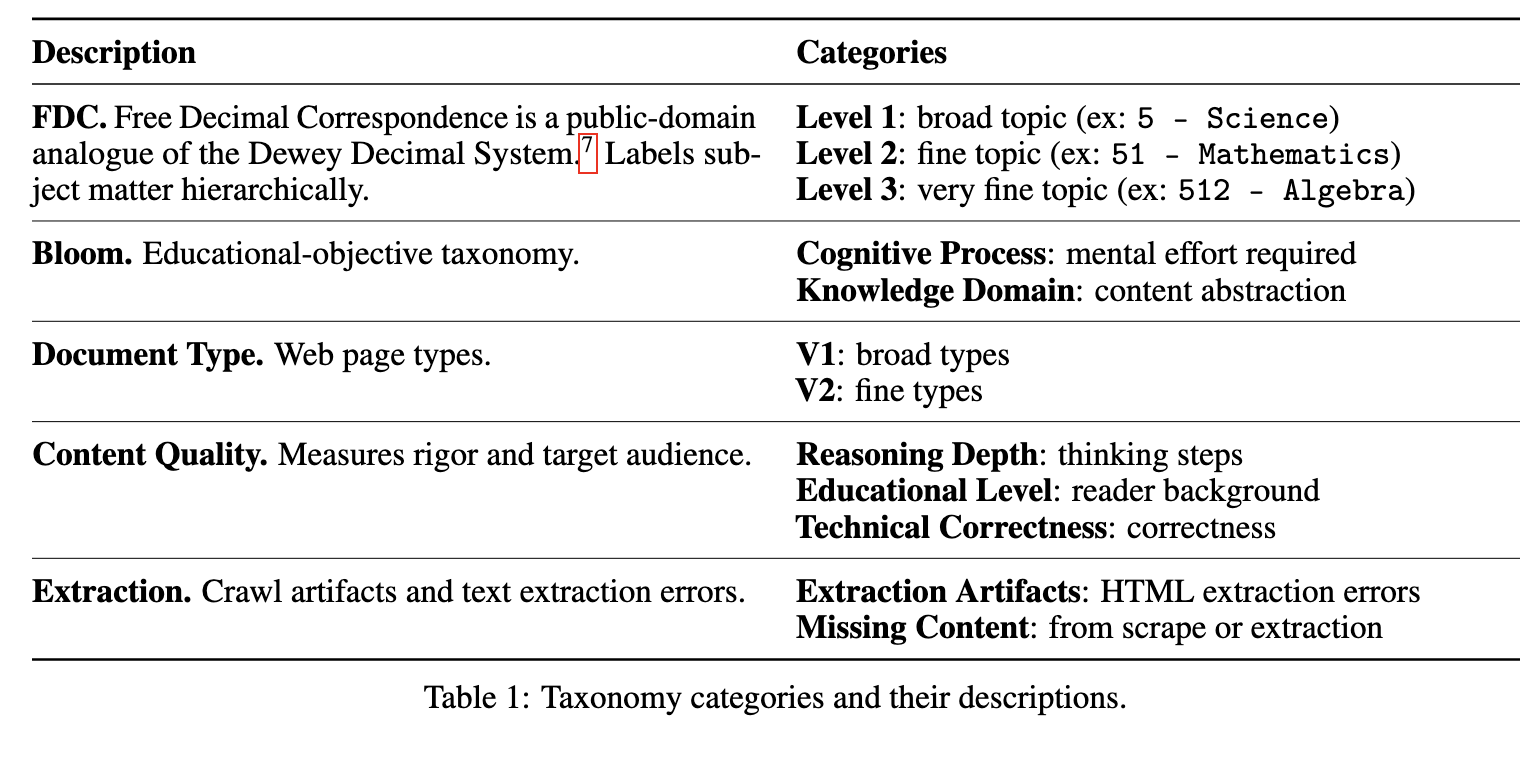
They use powerful open-weight LLMs to synthetically label web documents with a 12-category taxonomy
-
Taxonomy evaluation toolkit. They introduce a metric suite of normalized mutual information (NMI) to gauge category independence, annotator agreement using a variant of Cohen’s κ to ensure clear decision boundaries between category labels, and domain-recall to measure how well we recall high-value domains.
-
They release EAI-Distill-0.5b a 0.5B- parameter classifier produced by fine- tuning Qwen2.5-0.5b-Instruct using labels from Qwen-2.5-32B-Instruct.
- It labels the 23.6B document dataset in ≈90k MI300x GPU- hours while remaining within 3%, 14%, 1% of the teacher on annotator agreement, NMI, and domain-recall.
-
Simple SQL filters over the taxonomy produce datasets competitive with the best open-source, web-based baselines on math (-8.0% relative to SOTA), code (+14.3%), STEM (+24.5%).
The taxonomy
Overview
FDC (Free Decimal Correspondence)
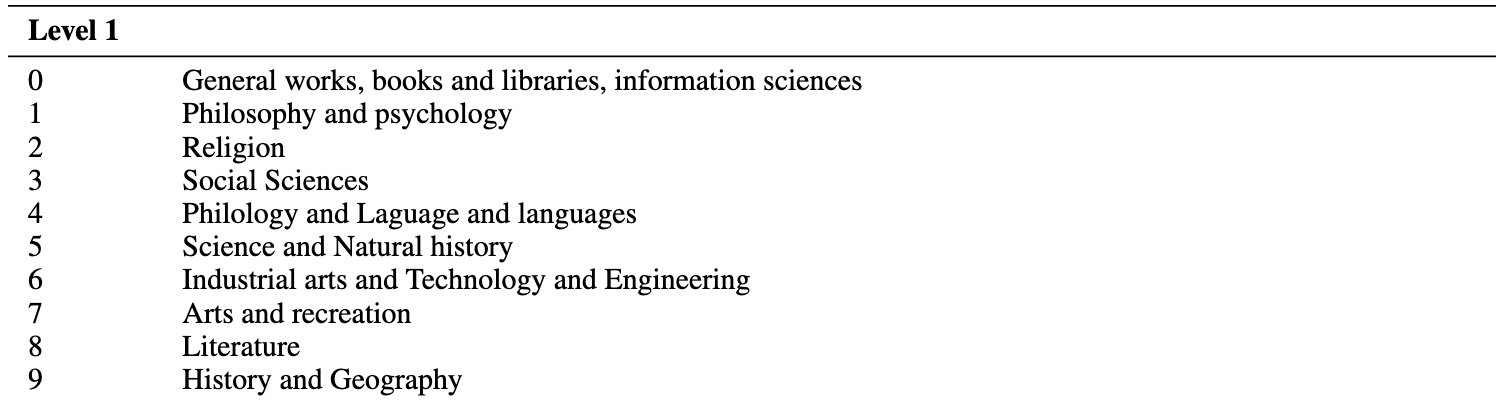
- It provides three nested categories – Level 1,2,3 – each successive level being a refinement of its parent
- Here is level 1
- Very useful to curate specific domains
- for Math,
FDC_KEEP = ["51"] # Mathematics - for code,
FDC_KEEP = ["004", "005"] # Computer Science and Software Development 61for medicine
- for Math,