-
It is obvious but the goal is to do a coarse to fine pipeline, where we will spend more compute at each step to iteratively improve quality while keeping costs and runtime contained.
-
For now, I will focus on text, and may extend later to discuss multimodal datasets
-
start with a large corpora
- e.g. for web data, 96 Common Crawl snapshots.
- or your own crawler
-
URL filtering
- to exclude domains related to adult, gambling content or just unrelated content
-
extract text from HTML
- In this step, you can get fancier depending on the topic you’re training for
- e.g. MegaMath made sure to convert and unify all math content (Katex, MathML, and unicode to LaTeX)
- In this step, you can get fancier depending on the topic you’re training for
-
base filtering
- fastText classifier to recall relevant documents
- maybe you want english-only
- or you want math documents
- quality and repetition filters (e.g. the ones from MassiveText)
- e.g. can use blacklists to remove adult content
- fastText classifier to recall relevant documents
-
Deduplication
- use Minhash and LSH, more explanation in Data deduplication
-
custom filtering
- examples are (from C4):
- dropping lines without a terminal punctuation mark, that mentioned javascript, or that had “terms-of-use”/“cookie policy” statements
- dropping documents that were too short or that contained “lorem ipsum” or a curly bracket ({).
- examples are (from C4):
-
LLM scoring
- can first collect scores for large model, and then finetune small model on such scores for less expensive scoring
-
LLM refining
- rephrasing
- or synthetic data e.g. extracting Q&A pairs like MAmmoTH2 - Scaling Instructions from the Web
Text extraction
-
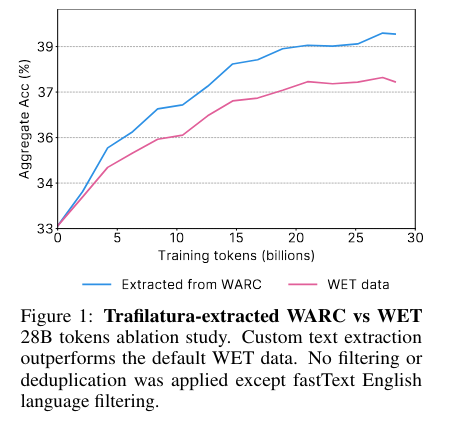
Common Crawl data is available in two different formats: WARC and WET
- WARC (Web ARChive format) files contain the raw data from the crawl, including the full page HTML and request metadata.
- WET (WARC Encapsulated Text) files provide a text-only version of crawled websites by using htmlparser
-
We can extract the text content from the WARC files using the open source trafilatura library
- A FineWeb ablation seems to indicate that it is better than using WET files